Apache DataFusion Comet#
A high-performance accelerator for Apache Spark
Speeds up your existing Spark queries by running them on Apache Arrow columnar data with Apache DataFusion, no code changes required. Also accelerates Parquet scans for Apache Iceberg.
# Add the Comet jar to your existing Spark job — no code changes
$ $SPARK_HOME/bin/spark-shell \
--jars comet-spark-spark4.1_2.13-1.3.0-SNAPSHOT.jar \
--conf spark.plugins=org.apache.spark.CometPlugin \
--conf spark.shuffle.manager=org.apache.spark.sql.comet.execution.shuffle.CometShuffleManager \
--conf spark.memory.offHeap.enabled=true \
--conf spark.memory.offHeap.size=4g \
--conf spark.executor.memoryOverhead=2g

// Your existing queries now run with Comet and DataFusion
scala> spark.sql("SELECT category, COUNT(*) FROM events GROUP BY category").show()
scala> ▍
Classpath and advanced tuning flags are covered in the installation guide.
Run Spark Queries at DataFusion Speeds
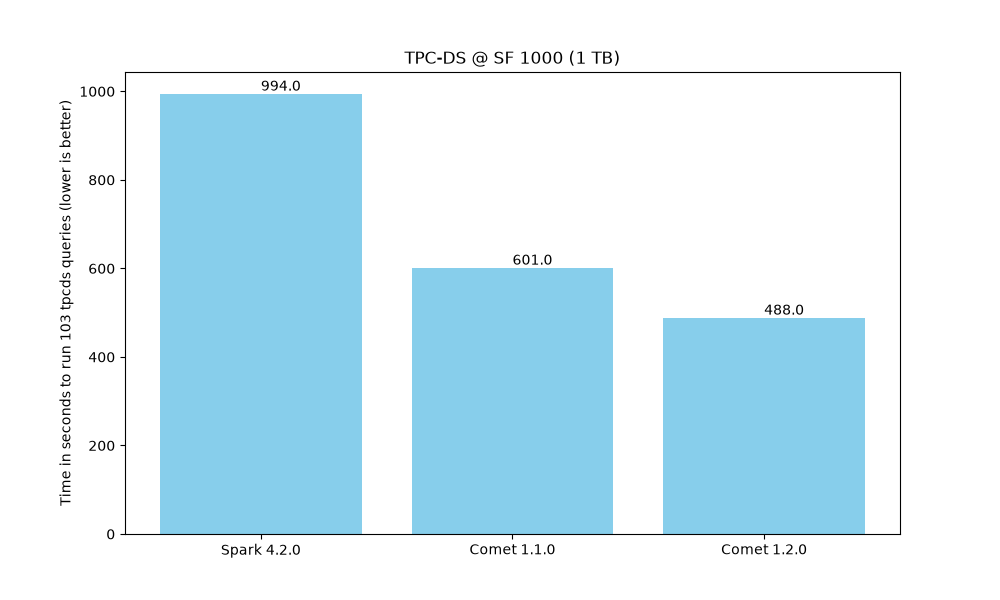
Comet delivers a performance speedup for many queries, enabling faster data processing and shorter time-to-insights.
The chart below shows Comet accelerating TPC-DS @ 1 TB. See the Comet Benchmarking Guide for the full per-query breakdown and reproduction methodology.
Spark Compatibility
100% compatibility with supported Spark versions.
Comet aims for 100% compatibility with all supported versions of Apache Spark, so you can add Comet to existing Spark deployments and workflows without changing any code. The Comet extension automatically detects unsupported features and falls back to the Spark engine.
Use Commodity Hardware
No GPUs. No FPGAs. No vendor lock-in.
Comet leverages commodity hardware, eliminating the need for costly hardware upgrades or specialized hardware accelerators, such as GPUs or FPGA. By maximizing the utilization of commodity hardware, Comet ensures cost-effectiveness and scalability for your Spark deployments.
Architecture
Tight integration with Apache DataFusion.
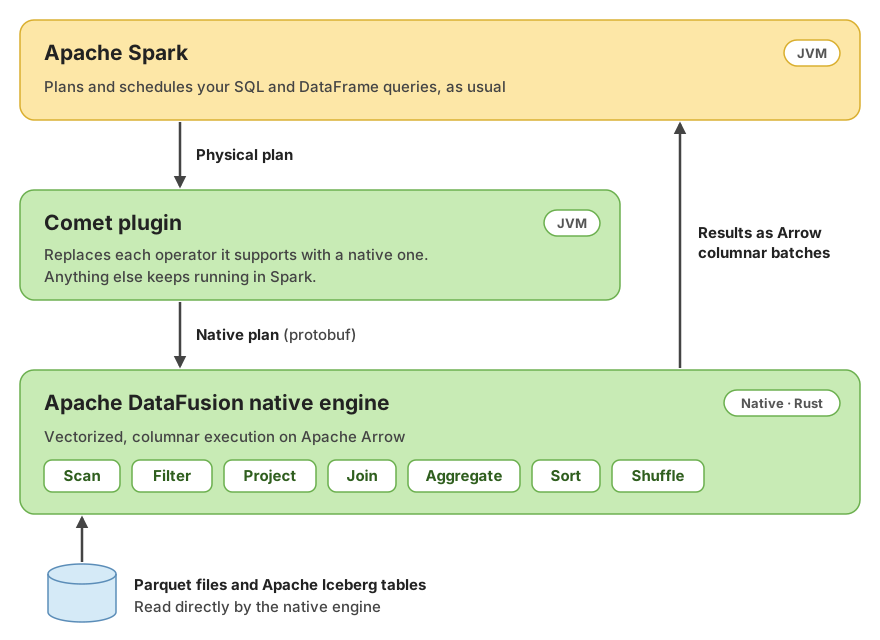
Comet tightly integrates with the core Apache DataFusion project, leveraging its execution engine. The diagram below shows how the Comet plugin intercepts Spark physical plans, translates the operators it runs in Rust into a protocol-buffer representation, and hands those to Apache DataFusion.
Getting Started
To get started with Apache DataFusion Comet, follow the installation instructions. Join the DataFusion Slack and Discord channels to connect with other users, ask questions, and share your experiences with Comet.
Contributing
We welcome contributions from the community to help improve and enhance Apache DataFusion Comet. Whether it's fixing bugs, adding new features, writing documentation, or optimizing performance, your contributions are invaluable in shaping the future of Comet. Check out our contributor guide to get started.